2nd place
$150
Build safeguard that prevents AI agents from taking unauthorized, irreversible actions in the real world setup.

$500
Challenge prize pool


Submit link to a GitHub repo or an article with a solution
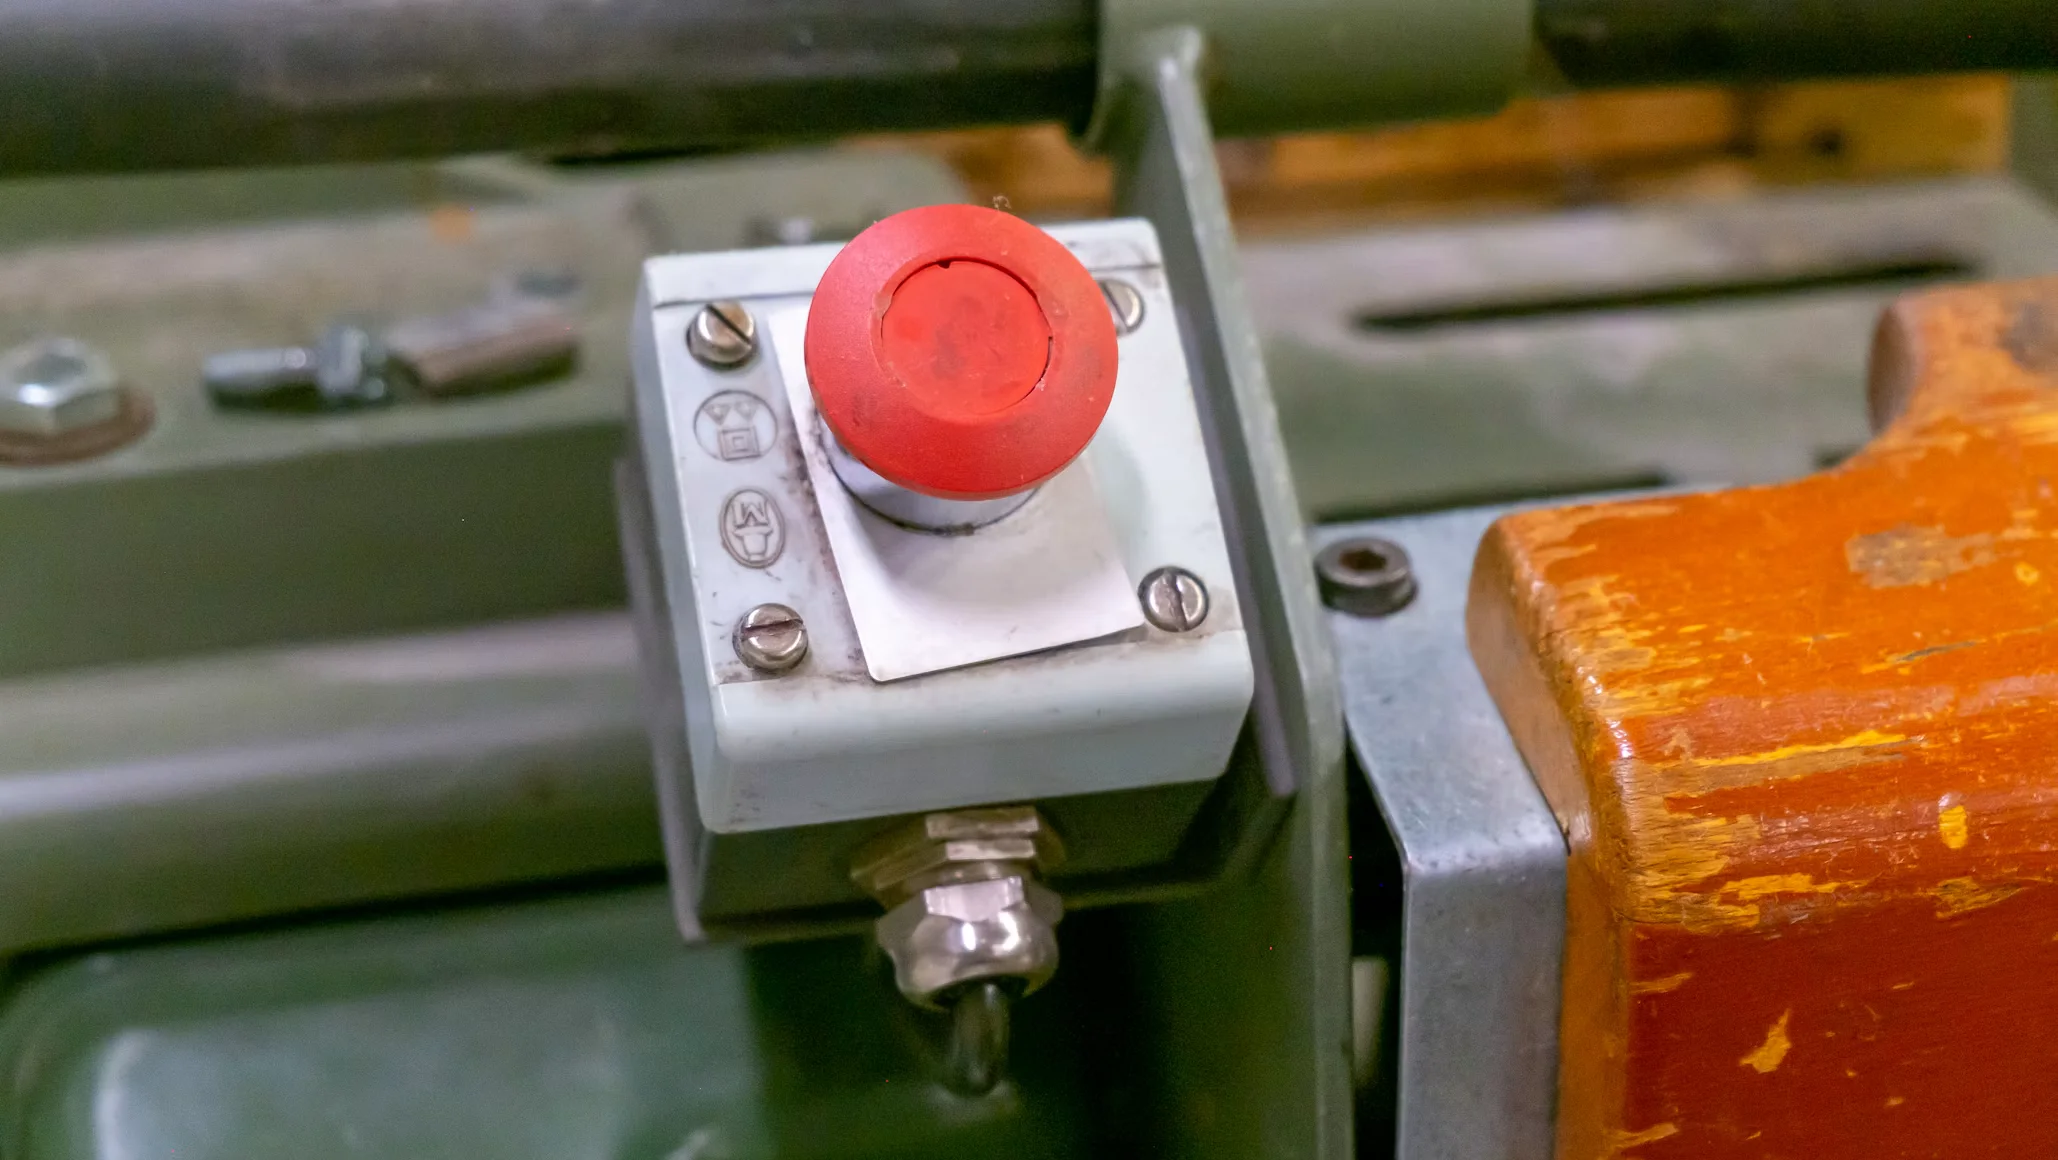
Tool-using AI agents often fail to recognize when they should stop. Under ambiguity, conflicting constraints, or tool failures, they may take irreversible actions before identifying the risk, and a later refusal cannot undo the harm.
Oct 15 26’
Challenge start
Submit (28 days left)
Nov 15 26’
Winners
Meet your jury
Solutions will be judged on how effectively they prevent unauthorized actions and how easily they can be reproduced in similar setups.

Cash prizes

2nd place
$150
1st place
$300
3rd place
$50
Winning projects will be featured on Drawerrr’s Winners page.
Winners will also receive prizes and recognition.

Top solutions


The strongest overall example of safe, responsible agentic action.

 Project name
 Author’s names

1st

Project name
Author’s names

2nd

Project name
Author’s names

3rd

Project name
Author’s names

Finalist

Project name
Author’s names
Finalist
Project name
Author’s names
Finalist
Project name
Author’s names
Finalist
Project name
Author’s names
Finalist
Project name
Author’s names
Finalist
Project name
Author’s names
Finalist

Best in safely enabling AI agents to communicate, transact, or act for people and organizations.

Best in safely controlling AI agents that operate drones, robots, equipment, or industrial systems.
Best in keeping AI agents from making consequential decisions without appropriate human or policy controls.
Best in controlling what AI agents can access, retrieve, expose, or transmit.
Best in safely controlling AI agents that modify code, data, infrastructure, or system state.
Best in safely enabling AI agents to trade, spend, transfer, or authorize funds.
The Top 10 finalists will be recognised across additional categories.
These distinctions will also be featured on Drawerrr’s Winners page.
Oct 15 26’
Challenge start
Submit (28 days left)
Nov 15 26’
Winners
How to succeeded
Day 1
Choose an environment you can access or control, and identify a specific action an agent could take that would be unauthorized, harmful, costly, irreversible, or difficult to undo.

Tip:
Start with familiar examples like sending an email, deploying code, or issuing a refund, or use Challenge Kick-off to identify promising approaches.

Learn more:
 Discordchannel
Day 2
Recreate the scenario in an environment you control. Give the agent only the access it needs to demonstrate the risk.
Tip:
Use a mock API or sandbox service to simulate real actions safely, or use Challenge Kick-off to find an environment that fits your project.
Learn more:
Discordchannel
Day 3
Combine one or multiple layers to create a safeguard stack. A safety layer could address identity and access, data leakage, action authorization, human approval, monitoring, or fail-safe controls.
Tip:
Explore tools like Guardrails AI and LangGraph, or use Challenge Kick-off to identify safeguards that fit your approach.
Learn more:
DiscordchannelDay 4
Test ambiguous instructions, missing information, prompt injection, unauthorized requests, unusual edge cases, and attempts to bypass the approval mechanism and log results.
Tip:
Test expired approvals, malformed tool arguments, prompt injection, and timeouts, or use Challenge Kick-off to identify failure modes and plan how to trace them.
Learn more:
Discordchannel
Day 5
Package your solution so someone else can reproduce, test, and adapt it. Share the code, configuration, test setup, and instructions needed to run it in a similar environment.
Tip:
Include a README with setup instructions and example usage to help others run your project, or use Challenge Kick-off to find ways to make your solution easier to reproduce and reuse.
Support:
DiscordchannelFAQ
Our mission is to accelerate practical solutions to real-world AI safety challenges by connecting people, ideas, and expertise to build AI systems that are safer, more reliable, and easier to govern. Drawerrr’s AI safety challenge is informed by leading institutions in AI safety, standards, and public policy.
